Today’s lead · TechCrunch
Meta makes its frontier-model move with Muse Wonder
Meta’s Wonder is the company’s first claimed frontier-class release, not just another low-latency Muse variant. The practical question is whether its “active memory” and coding strength hold up outside Meta’s benchmarks; Vercel’s AI Gateway already gives builders a lower-friction path to try Wonder without a separate Meta account.

Top signals
9 more
MiniCPM-V 4.7 pushes open multimodal models onto phones
MiniCPM-V 4.7 is interesting because its pitch is not just benchmark-chasing: OpenBMB is aiming a 35B-A3B MoE and a 1B multimodal model at local devices. The headline claim is LES, which preloads expert weights to reduce stalls without changing outputs.

Microsoft’s Maia bet shifts the bottleneck from chips to the stack
Microsoft is framing Maia as its “biggest bet yet” on in-house silicon, with multi-gigawatt inference deployments planned next calendar year. For builders, the silicon is only half the story: the compiler, kernel DSL, runtime, and migration path will decide whether tokens-per-watt claims translate into usable capacity.

AMD’s Helion rack targets the economics of agent workloads
AMD’s Helion is less about one faster accelerator and more about rack-level flexibility for agent workloads that mix cheap routing, CPU-heavy steps, and GPU calls. The useful idea is the token router; the open question is whether partner racks ship on time and beat proprietary stacks on operating cost.

Intel samples a memory-heavy GPU D-Series for inference
Intel’s GPU D-Series, formerly Crescent Island, is positioned around inference memory capacity rather than HBM-style peak bandwidth. That could matter for long context and high-concurrency agents where KV cache dominates, but the supplied details still leave quantization assumptions and real workload performance unresolved.

OpenAI moves code review workflow into Codex
OpenAI’s demo turns Codex into a code-review inbox rather than just a coding assistant. The useful shift is consolidation: GitHub PRs, automatic cloud reviews, private chats, repository context, custom instructions, and review actions all sit in one workflow, with GitHub Code Review generally available and GitLab support in preview.
Vivix W1 makes real-time video pricing the story
Vivix W1 is worth watching because its claimed $0.003-per-output-second price changes what people can afford to prototype: interactive stories, games, and live visuals rather than isolated clips. The caveat is clear in the source too: complex motion and dense scenes still need scrutiny.
SubQ Snap carves out cheap long-context decisions for agents
SubQ Snap’s pitch is a useful distinction for agent builders: not every step needs open-ended generation. If its claimed subquadratic scaling and benchmark lead hold up, a cheap structured decision model could handle routing, ranking, filtering, and yes/no calls before escalating only hard work to frontier LLMs.
Streaming Code World Model opens code and checkpoints for causal video worlds
Streaming Code World Model turns CWM into a causal, chunk-by-chunk generator from a live proxy, with code and checkpoints available. It is not real-time yet: the released 4-step distilled model renders a 0.71-second chunk in about 5.1 seconds on one H200.

Claude Code shows up in an active initial-access campaign
The CyberXero report is a concrete reminder that AI coding agents are already being wired into offensive workflows, not just discussed hypothetically. The notable detail is mixed: Claude Code allegedly helped orchestrate scanning and exploitation, while logs also showed refusals that held against some backdoor and lateral-movement requests.
Tools & repos
3 selected
guilds.run
Open-source multi-agent workflows with inspection built in: prompts, tool calls, memory changes, and agent interactions are visible. The self-hosting angle matters if your team needs control before trusting agent teams.
Base Code
Base Code brings browser-based plain-language changes to existing codebases, then routes completed work through normal pull requests. The useful promise is team access without bypassing GitHub review flow.
Manifold MCP
A hosted MCP server that gives agents live marketing data across SEO, AI answers, social, ads, Reddit, and leads. Useful if your workflow is already inside Claude, ChatGPT, Cursor, or Claude Code.
Blogs worth your time
3 reads
ReplaySSM makes hybrid-model decoding less memory-bound
NVIDIA and Princeton’s Dao AI Lab explain ReplaySSM: cache recent SSM inputs instead of rewriting full state every token. The payoff is faster decoding, cleaner speculative rollback, and safer low-precision state reads for hybrid models.

Microsoft Research uses simulated students to stress-test AI tutors
StudentSim is a research system, not a classroom product. The useful idea is early tutor evaluation: simulate specific learners’ answers and reactions to guidance before spending time and risk on real student studies.
GitHub’s practical guide to teaching Copilot your repo rules
This is basic but valuable operational hygiene for coding agents: put repo conventions, repeatable procedures, specialist agents, and MCP tool access where Copilot can find them automatically instead of re-prompting from scratch.
Community discussions
3 threadsICLR reviewers are debating AI-written papers versus actual research quality
The thread’s useful tension: reviewers dislike AI slop, but several argue the real criterion is not detectable AI prose; it is missing baselines, shallow claims, messy appendices, and whether the work is thorough enough to evaluate.
A mechanistic AGI debate tries to get past scale-curve faith
The original question asks for a causal, learning-theory-level case that today’s next-token-plus-RL systems can become open-ended general intelligence. The comments mostly expose the gap: definitions, evidence from human cognition, and efficiency comparisons are still deeply unsettled.
Claude Code users split on whether Opus 5.5 is reasoning or just great execution
A Claude Code user says Opus 5.5 feels less like serious reasoning over time; replies push back with concrete automation, hardware debugging, and coding examples. The takeaway is familiar: satisfaction depends heavily on task framing, effort level, and expectations.
Funding & acquisitions
0 movesNothing material cleared the editorial bar today.
Bengaluru radar
1 events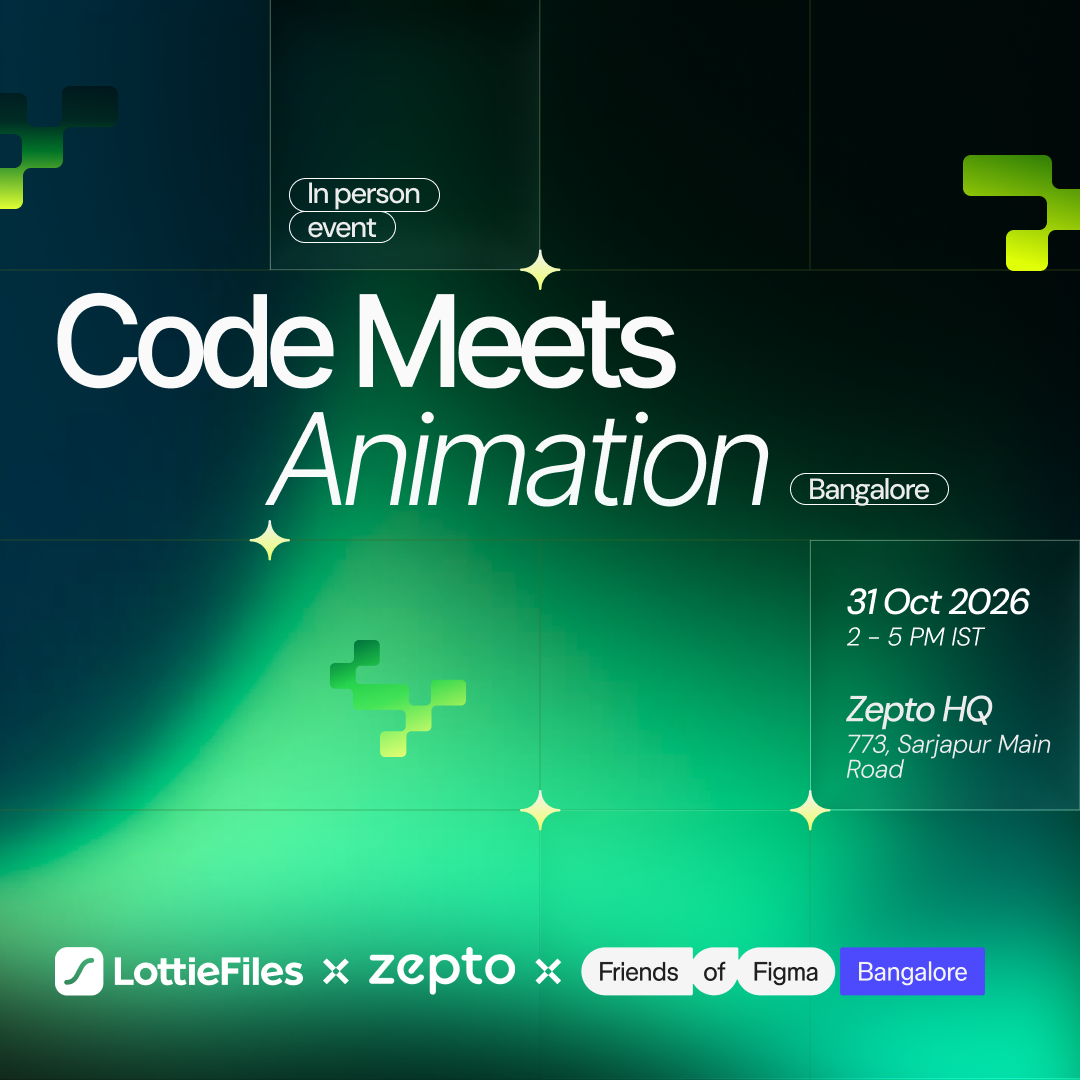
Code Meets Animation - Bangalore
LottieFiles, Zepto, and Friends of Figma Bangalore are hosting talks, networking, and a prompt-only UI animation challenge. Bring a laptop if you want to participate.